덤프의 세가지 버전
CompTIA CompTIA Data+덤프를 구매하시면 시스템 자동으로 덤프파일 다운로드 링크가 고객님 메일주소에 발송됩니다. DY0-001덤프는 세가지 버전으로 되어있는데 PDF버전을 구매하시는 분이 가장 많습니다. PDF버전을 공부하신후 DY0-001시험환경을 체험해보고 싶으시다면 소프트웨어버전이나 온라인버전을 추가구매하시면 됩니다. DY0-001덤프를 PC에서 사용하시려면 소프트워어버전을 구매하시면 되고 휴대폰으로 공부하고 싶으신 분은 DY0-001 덤프의 온라인버전을 구매하시면 됩니다.
시중에서 가장 최신버전자료 제공
DY0-001덤프의 도움으로 여러분은 많은 시간과 돈을 들이지 않으셔도 혹은 학원등록을 하지 않으셔도 DY0-001덤프로 안전하게 시험을 통과하실 수 있습니다.덤프문제는 50문항으로 부터 1000문항 등 매 과목보다 문항수가 다른데 거의 2,3일이면 대부분 문제를 마스터 할수 있습니다. DY0-001최신덤프는 DY0-001실제시험 기출문제에 대비하여 만들어진 퍼펙트한 자료로서 시험적중율이 높아 많은 IT업계 인사들에서 자격증을 안겨드렸습니다.
덤프무료샘플 문제 다운가능
IT인증자격증을 취득할수 있는 DY0-001인기시험을 어떻게 패스할가 고민그만하시고 저희 IT전문가들이 제작한 DY0-001 인기덤프자료를 데려가 주세요. CompTIA CompTIA Data+ 시험덤프자료는 가격이 착한데 비해 너무나 훌륭한 품질과 높은 적중율을 지니고 있습니다. DY0-001 인기덤프자료 덤프구매전 데모부터 다운받아 공부해보세요.데모문제는 덤프에 포함되어 있는 문제기에 덤프품질 체크가 가능합니다.
CompTIA DY0-001 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| 주제 2 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| 주제 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| 주제 4 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| 주제 5 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
참조: https://www.comptia.org/en-us/certifications/dataai/
최신 CompTIA Data+ DY0-001 무료샘플문제
문제 #1
A data scientist trained a model for departments to share. The departments must access the model using HTTP requests. Which of the following approaches is appropriate?
A. Create an endpoint.
B. Utilize distributed computing.
C. Deploy containers.
D. Use the File Transfer Protocol.
문제 #2
A data scientist is using the following confusion matrix to assess model performance:
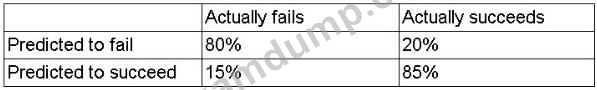
The model is predicting whether a delivery truck will be able to make 200 scheduled delivery stops. Every time the model is correct, the company saves an hour in planning and scheduling of maintenance work. Every time the model is wrong, the company loses four hours of delivery time for the truck. Which of the following is the net model impact for the company?
A. 25 hours lost
B. 165 hours lost
C. 165 hours saved
D. 25 hours saved
문제 #3
A data analyst wants to save a newly analyzed data set to a local storage option. The data set must meet the following requirements:
Which of the following file types is the best to use?
A. XML
B. Parquet
C. JSON
D. CSV
문제 #4
A data analyst is examining the correlation matrix of a new data set to identify issues that could adversely impact model performance. Which of the following is the analyst most likely checking for?
A. Oversampling
B. Multicollinearity
C. Overfitting
D. Undersampling
문제 #5
A data scientist is deploying a model that needs to be accessed by multiple departments with minimal development effort by the departments. Which of the following APIs would be best for the data scientist to use?
A. RPC
B. SOAP
C. JSON
D. REST
질문과 대답:
문제 #1
정답: A | 문제 #2
정답: A | 문제 #3
정답: B | 문제 #4
정답: B | 문제 #5
정답: D |


 PDF Version DEMO
 자격증의 중요성:경쟁율이 심한 IT시대에 인증시험을 패스함으로 IT업계 관련 직종에 종사하고자 하는 분들에게는 아주 큰 가산점이 될수 있고 자신만의 위치를 보장할수 있으며 더욱이는 한층 업된 삶을 누릴수 있을수도 있습니다.
 ITExamDump 제품의 가치:ITExamDump에는 IT인증시험의 최신 학습가이드가 있습니다. ITExamDump의 IT전문가들이 자신만의 경험과 끊임없는 노력으로 최고의 학습자료를 작성해 여러분들이 시험에서 패스하도록 도와드립니다.
 무료샘플 받아보기:관심있는 인증시험과목 덤프의 무료샘플을 원하신다면 덤프구매사이트의 PDF Version Demo 버튼을 클릭하고 메일주소를 입력하시면 바로 다운받아 덤프의 일부분 문제를 체험해 보실수 있습니다.
 완벽한 서비스 제공:ITExamDump는 한국어로 온라인상담과 메일상담을 받습니다. 덤프구매후 일년동안 무료 업데이트 서비스를 제공해드리며 구매일로 부터 60일내에 시험에서 떨어지는 경우 덤프비용 전액을 환불해드려 고객님의 부담을 덜어드립니다.


